Bryan Falkowski
Work
Papers, projects and notes on evaluating AI and building with coding agents. Most of it has code you can run.
Papers and primers
-
Checking whether an eval run worked before trusting its score.
-
Measuring and correcting LLM judge scores, with a customer service politeness example.
-
Can a Browser Test Agent Tell When It Can't Tell? Ambiguity and Calibration in Element SelectionPaper, Sep 2026
Whether LLM test agents refuse when the target element is missing or ambiguous.
-
LLM-as-a-Judge Repeat Stability with MT-BenchM.S. capstone, RIT
How consistently LLM judges reproduce scores across repeated runs.
Projects
In progress
Exhibit
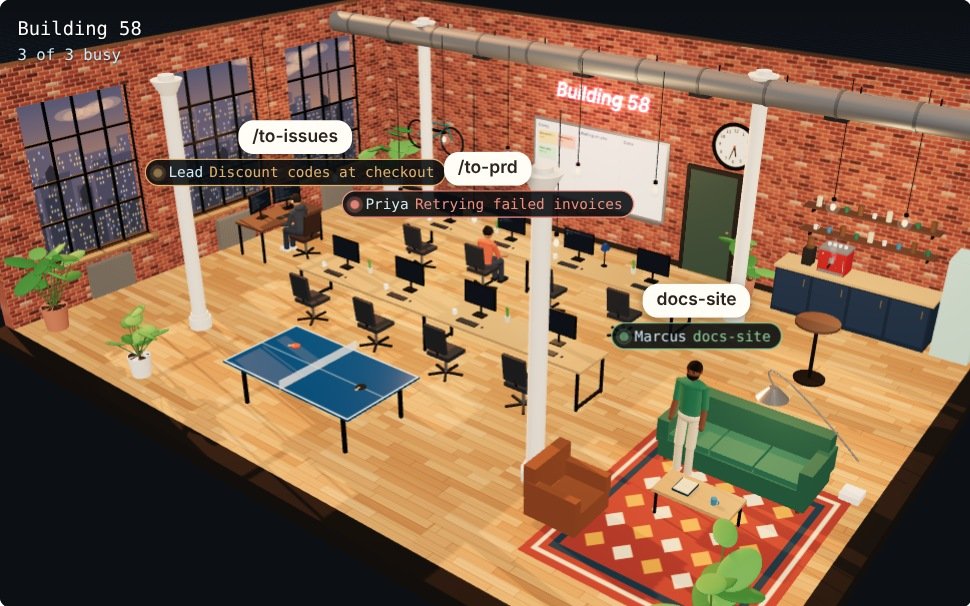
Decides what evidence a pull request needs, checks it, and learns its rules from bugs that got through. Built by a Building 58 room.
CodeEval Run Validity Gate
Checks whether an eval run is valid before its score is trusted.
CodeEvaluation-Driven Design Platform
A deployable system for building, testing and improving AI agents. Room B uses it as a new user would.
CodeBrowser Agent Dashboard
Compares a purpose-built decision model with a Claude agent on the same browser test.
CodeLLM Evaluation Service Stack
A containerized service for running LLM evaluation jobs, with a console and Kubernetes deployment.
CodeNotes
Stories
Short story and short film
Doctor Bones
A short story inspired by Player Piano, then a 3D kitchen world and a first-draft film made in one day with AI tools.
Read the storyFilms
Building 58 trailers
The people edition and the robot edition, each in 3D and realistic versions.
Watch